Isaac Skill Lab
Pick-and-place skill training and evaluation in NVIDIA Isaac Sim / Isaac Lab: own scene, Franka with a differential-IK controller, scripted demonstrations from 1024 parallel environments, behaviour cloning, and an evaluation harness with held-out seeds, confidence intervals and paired tests.
NVIDIA L4, Isaac Sim 4.5 / Isaac Lab 2.1.1, simulation only, no real robot
Code: https://github.com/pavanyadava007/isaac-skill-lab
Learned BC-MLP policy on held-out seeds, rendered with an Isaac Lab camera (simulation only).
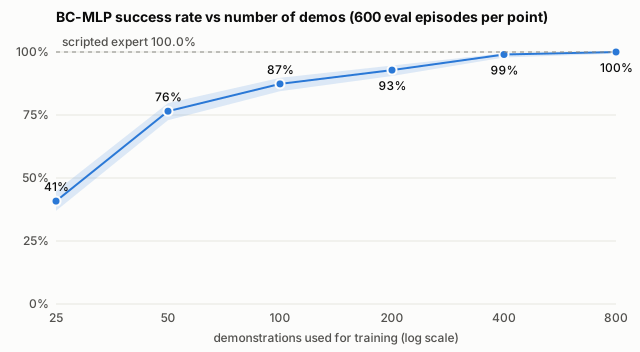
Data scaling
| demos | success (3 seeds x 200 episodes) | mean time to success |
|---|---|---|
| 25 | 40.8% (245/600, CI 37.0% to 44.8%) | 5.21 s |
| 50 | 76.5% (459/600, CI 72.9% to 79.7%) | 4.98 s |
| 100 | 87.3% (524/600, CI 84.4% to 89.8%) | 5.01 s |
| 200 | 92.8% (557/600, CI 90.5% to 94.6%) | 4.99 s |
| 400 | 99.0% (594/600, CI 97.8% to 99.5%) | 4.80 s |
| 800 | 100.0% (600/600, CI 99.4% to 100.0%) | 4.75 s |
| scripted expert | 100.0% (200/200, CI 98.1% to 100.0%) | 4.80 s |
Demos kept: 1004 / 1024 expert episodes (98.0%), executed with DART-style noise. Total training time for all runs: 16.0 min.
BC-MLP vs BC-RNN
| demos | BC-MLP | BC-RNN | McNemar p |
|---|---|---|---|
| 100 | 87.3% (524/600, CI 84.4% to 89.8%) | 99.8% (599/600, CI 99.1% to 100.0%) | 5.3e-23 |
| 400 | 99.0% (594/600, CI 97.8% to 99.5%) | 100.0% (600/600, CI 99.4% to 100.0%) | 0.031 |
Robustness (success rate)
| agent | nominal | wide_pose | heavy_slippery | obs_noise_5mm | action_delay_1 | action_delay_2 | small_cubes |
|---|---|---|---|---|---|---|---|
| scripted expert | 100.0% | 100.0% | 100.0% | 100.0% | 3.5% | 0.0% | 100.0% |
| BC-MLP 800 demos | 100.0% | 99.3% | 100.0% | 99.7% | 7.5% | 0.0% | 99.8% |
| BC-RNN 400 demos | 100.0% | 99.8% | 100.0% | 100.0% | 4.8% | 0.0% | 100.0% |
| BC-MLP 400, no DR | 75.0% | 74.5% | 70.0% | 99.0% | 9.3% | 0.0% | 19.3% |
Shifted conditions: larger pose area, heavier and more slippery cube, 5 mm observation noise, 1 or 2 step (50 or 100 ms) action delay, cubes smaller than in training. Policies pool 3 training seeds.
Domain randomization vs none
| test world | trained with DR | trained without DR | McNemar p |
|---|---|---|---|
| DR ranges (nominal) | 99.0% (594/600, CI 97.8% to 99.5%) | 75.0% (450/600, CI 71.4% to 78.3%) | 7.7e-39 |
| heavy and slippery | 98.3% (590/600, CI 97.0% to 99.1%) | 70.0% (420/600, CI 66.2% to 73.5%) | 1.1e-43 |
| wide pose | 94.8% (569/600, CI 92.8% to 96.3%) | 74.5% (447/600, CI 70.9% to 77.8%) | 3.6e-23 |
| small cubes | 94.8% (569/600, CI 92.8% to 96.3%) | 19.3% (116/600, CI 16.4% to 22.7%) | 6.3e-130 |
| no-DR world (fixed physics) | 99.7% (598/600, CI 98.8% to 99.9%) | 99.3% (596/600, CI 98.3% to 99.7%) | 0.69 |
Limitations
- Simulation only; no real robot, no sim-to-real claim.
- State-based observations (exact object poses), no camera input to the policy.
- Scripted demonstrations, not teleoperation.
- The delta-action interface oscillates under actuation delay, for the expert and the learned policies.